Tiny Search Engine
A crawler, indexer, and ranked query engine built in C.
Three command-line stages
The project separates crawling, indexing, and querying. The crawler writes numbered page files, the indexer builds an inverted index from those files, and the querier loads the index and reads searches from standard input. The stages communicate through the page-directory and index-file formats.
Indexing the page directory
The indexer validates the crawler marker and numbered document files, loads each saved page, normalizes words, ignores words shorter than three characters, and records each document ID and word count. The resulting index supports word-to-document lookup without revisiting the source pages.
Boolean queries and ranking
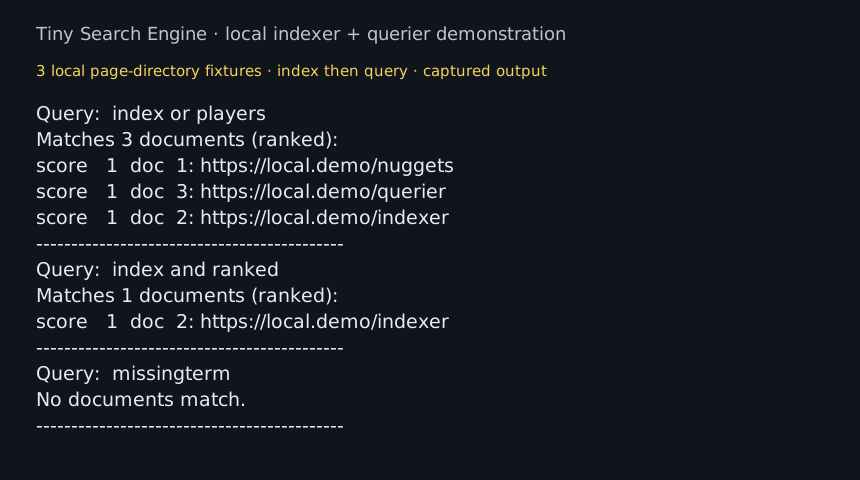
The querier tokenizes and lowercases input, rejects malformed operator placement, intersects document counters for AND groups, and combines groups for OR. It prints the matching document URLs in descending score order. In the recorded local run, “index or players” matched all three fixture documents; “index and ranked” returned one; a missing term returned no matches.
C modules and validation
The programs use reusable C containers for bags, counters, hash tables, and sets, plus common modules for page directories, words, and indexes. Argument checks guard unreadable directories, missing crawler markers, and bad index paths. The restored source includes component test scripts and design notes for the crawler, indexer, and querier.